Your phone is not a GPU
What happens to small models when the phone gets warm
Every new small model arrives with a benchmark score. Almost none of those scores were measured on a phone. I ran four of them on my Pixel 7a for two weeks, and the order they finish in is not the order the leaderboards promise.
"Benchmarks are the rulers of AI, in both senses of the word." (Quanta Magazine)
What I measured
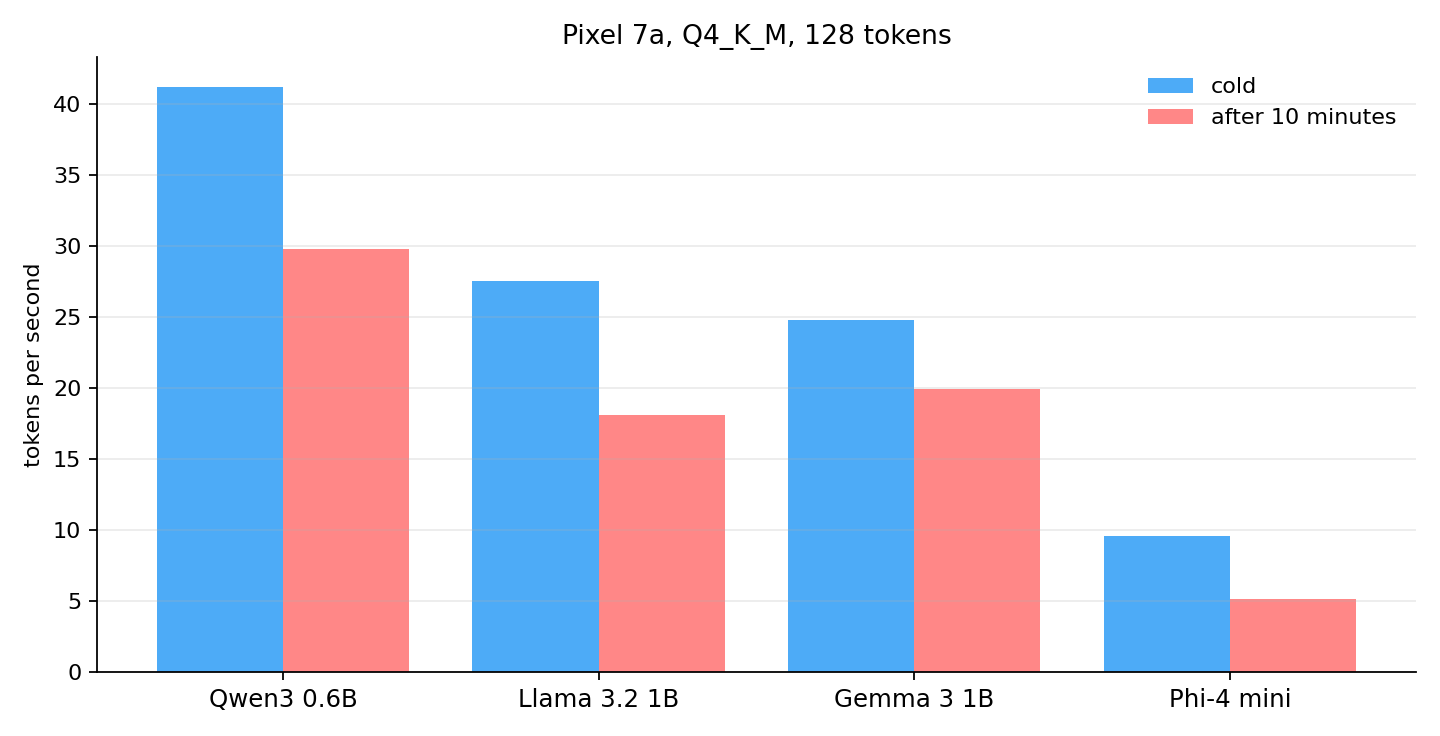
Each model ran in llama.cpp at Q4_K_M, 128 new tokens, first on a cold phone and again after ten minutes of steady use.
| Model | Size | Cold (tok/s) | Warm (tok/s) | Drop | Pixel 8 warm (tok/s) |
|---|---|---|---|---|---|
| Qwen3 0.6B | 0.4 GB | 41.2 | 30.2 | -28% | 36.4 |
| Llama 3.2 1B | 0.8 GB | 27.5 | 18.1 | -34% | 24.0 |
| Gemma 3 1B | 0.8 GB | 24.8 | 19.9 | -20% | 25.7 |
| Phi-4 mini | 2.4 GB | 9.6 | 5.2 | -46% | 7.9 |
Why the rankings flip
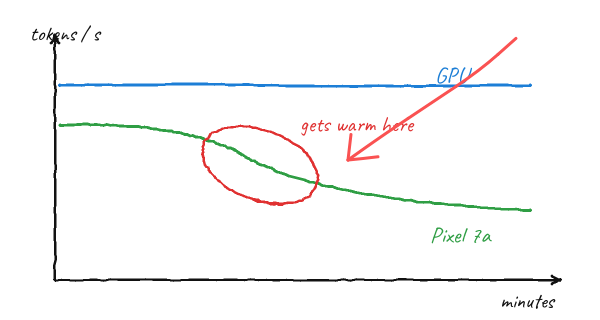
A data-center GPU runs at the same speed for hours. A phone has a few watts and no fan, so after a few minutes it throttles, and the bigger the model, the harder it falls.
- Memory bandwidth, not compute, sets the pace for one prompt at a time.
- Heat arrives after about four minutes, whatever the model.
- Small models lose less, because they finish before the phone warms up.
How to reproduce
Run this on a cold phone, then again after ten minutes of use:
./llama-bench -m qwen3-0.6b-q4_k_m.gguf -p 512 -n 128 -r 5Each run uses llama-bench with five repeats.
Before I publish
- Run every model five times
- Error bars on the chart
- Ask Dr. Okafor about the Pixel 8 numbers
- Pick a cover